
Predictive Behavioral Segmentation:
The €310M Compliance Reckoning
LinkedIn’s fine wasn’t bad luck. It was the logical endpoint of treating behavioral inference as a purely technical problem. Here’s what the enforcement record actually teaches—and what your stack needs to survive the August 2026 deadline.
The LinkedIn Precedent: When Behavioral Inference Becomes a €310M Liability
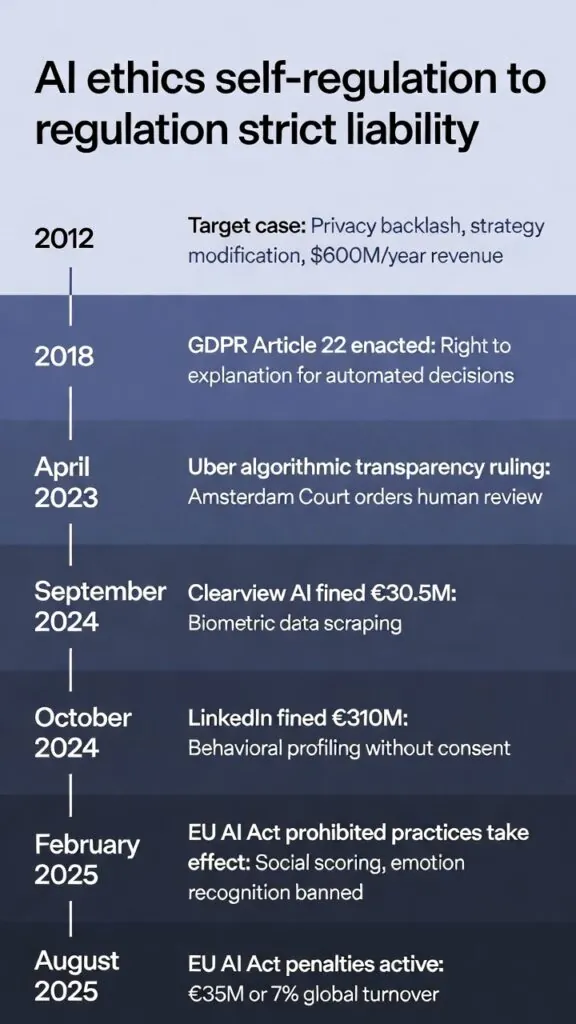
In October 2024, the Irish Data Protection Commission imposed a €310 million fine on LinkedIn for behavioral analysis and targeted advertising practices that exemplify just how precarious predictive segmentation has become. The investigation revealed that LinkedIn tracked not only standard social signals—likes, posts, subscriptions—but granular telemetry including how long users lingered on specific posts, scroll speed through feeds, and cross-device engagement patterns. These signals fed algorithms inferring “likelihood of professional burnout” and job-change propensity, which then drove targeted advertising and internal ranking systems without obtaining valid consent under GDPR Articles 5 and 6.
What makes this enforcement action especially significant isn’t the fine amount. It’s what the regulators decided counts as personal data. Behavioral telemetry—dwell time, scroll velocity—that engineers might classify as anonymous event logs is now firmly within GDPR’s scope when it infers psychological states associated with identifiable users. That changes the liability calculus for almost every personalization stack running today.
The Clearview AI enforcement from September 2024 adds another dimension: extraterritoriality. The Dutch Data Protection Authority fined Clearview AI €30.5 million for scraping over 30 billion facial images without consent to build a biometric identification database. Clearview, based in New York with no EU corporate presence, initially argued it fell outside GDPR jurisdiction entirely. The enforcement action confirmed that GDPR Article 3(2) applies to any AI system monitoring the behavior of EU residents, regardless of where processing occurs. If your segmentation stack touches EU users, you’re inside the tent whether you’re incorporated in Dublin or Delaware. → GDPR Guide
Target’s €600M Lesson: The Creepiness Threshold Was Always Structural
Before there were DPAs issuing nine-figure fines, there was Target. The foundational commercial precedent remains the pregnancy prediction algorithm developed between 2002 and 2010 by statistician Andrew Pole, who analyzed purchase histories from baby registry participants to identify 25 product categories indicating pregnancy—unscented lotion, calcium supplements, cotton balls, hand sanitizer. The algorithm predicted not only pregnancy status but approximate due dates, enabling timed marketing campaigns before competitors could intercept those customers. → Behavioral Analytics
Target’s revenue grew from $44 billion in 2002 to $67 billion in 2010, the period spanning Pole’s model rollout. A “$600 million in additional annual revenue” figure for the pregnancy-prediction program specifically circulates widely in marketing commentary — but when I checked it against Charles Duhigg’s original 2012 New York Times reporting, the primary source for this whole case, the number isn’t there, and I couldn’t trace it to any Target financial disclosure either. It appears to have entered circulation through later secondary sources and been repeated without a verifiable origin since. I’m noting that gap rather than repeating the figure as fact: the program’s actual revenue contribution, whatever it was, isn’t independently confirmable from public records.
Then came the 2012 Minneapolis incident. A father discovered his teenage daughter’s pregnancy through Target’s mailed coupons before she’d told anyone in her family. When predictive accuracy exposes the surveillance mechanism, relevance converts to reactance. Target subsequently modified its strategy to mix pregnancy-related coupons with unrelated offers—deliberately disguising the algorithmic precision while maintaining revenue capture. The lesson wasn’t “don’t predict.” The lesson was: visibility of the mechanism is a separate design variable from accuracy of the model. Twenty-four years later, GDPR enforcement has finally made that structural tension into a legal obligation, not just a brand risk.
Psychographic vs. Behavioral vs. Demographic: Where the Confusion Actually Costs You
Every enforcement action in this article turns on a distinction most teams never define precisely. “Behavioral segmentation” gets used as a catch-all for three fundamentally different kinds of customer data — and conflating them is exactly how a marketing team ends up building a “behavioral” model on inferred psychological traits without realizing it just walked into LinkedIn’s exposure. The three types answer different questions, come from different sources, and carry different compliance weight.
| Dimension | Demographic | Psychographic | Behavioral |
|---|---|---|---|
| What it measures | Who the person is — age, gender, income, education, location, job title | Why they buy — values, attitudes, personality, lifestyle, self-image | What they actually do — purchases, sessions, clicks, response to campaigns |
| Primary data source | Sign-up forms, panel data, third-party enrichment | Surveys, interviews, focus groups, social listening | Transaction logs, CRM, web/app analytics, POS data |
| Typical output | Static profile field | Persona or archetype | Propensity score, RFM tier, churn probability |
| Update cadence | Rarely changes (years) | Periodic refresh (quarterly/annual) | Continuous, often real-time |
| Question it answers | “Is this a 35–44 urban professional?” | “Does this person value convenience over price?” | “Has order frequency dropped 40% in 60 days?” |
| GDPR / AI Act exposure | Low — mostly declared attributes | Moderate — inferred traits can shade into sensitive categories | High — this is exactly what triggered the LinkedIn and Clearview fines above |
Psychographic in Practice: The Persona
Psychographic segmentation is built qualitatively, then expressed as a persona — a composite sketch used to guide messaging tone and creative direction rather than to trigger individual real-time decisions. A persona doesn’t update when a specific customer clicks a link; it’s a static reference document refreshed periodically as research is repeated.
Core value: Risk aversion over speed — Dana would rather spend three extra weeks validating a vendor than explain a bad choice to her CFO.
Attitude toward the category: Skeptical of vendor claims by default; trusts peer case studies and analyst reports over sales collateral.
Lifestyle / working style: Reads long-form technical content before demos; prefers async evaluation (docs, sandbox trials) over discovery calls.
Source of this profile: 14 customer interviews and a closed-lost survey — qualitative, not transactional.
Dana informs the tone and structure of a nurture sequence for everyone in a segment — not a real-time trigger for any individual account. That’s the structural difference from behavioral scoring below.
Behavioral in Practice: RFM Analysis
Where personas are qualitative and static, behavioral segmentation is quantitative and continuous. The oldest and still most widely deployed technique is RFM analysis — scoring every customer on Recency (how long since their last action), Frequency (how often they act), and Monetary value (how much they spend) — a direct-mail-era database marketing method that predates machine learning by decades and requires no survey data at all, only a transaction log.
| Segment | Recency | Frequency | Monetary | Typical Action |
|---|---|---|---|---|
| Champions | Purchased <30 days ago | 10+ orders/year | Top 20% of spend | Early access, no discount needed |
| Loyal Customers | Purchased <90 days ago | 5–9 orders/year | Mid-to-high spend | Loyalty-tier upsell |
| At Risk | No purchase in 180+ days | Was previously frequent | Was previously high | Win-back offer with incentive |
| Hibernating / Lost | No purchase in 365+ days | Low historical frequency | Low historical spend | Suppress from paid spend; low-cost reactivation only |
The practical …or protected-category signals, which is exactly what the LinkedIn and Amazon cases demonstrated. The key point is that a persona identifies your target audience for content, while an RFM tier indicates who should receive your emails today. Most advanced personalization practices…: a persona tells you who to write for; an RFM tier tells you who to email today. Most mature personalization programs run both in parallel — psychographic segmentation shaping creative and positioning, behavioral segmentation driving the real-time trigger logic covered in the next section. For a structured comparison of where AI-driven segmentation techniques fit across both categories, see our companion breakdown. → Top 7 AI Smart Segmentation Strategies
Signal → Score: The Three Technical Layers
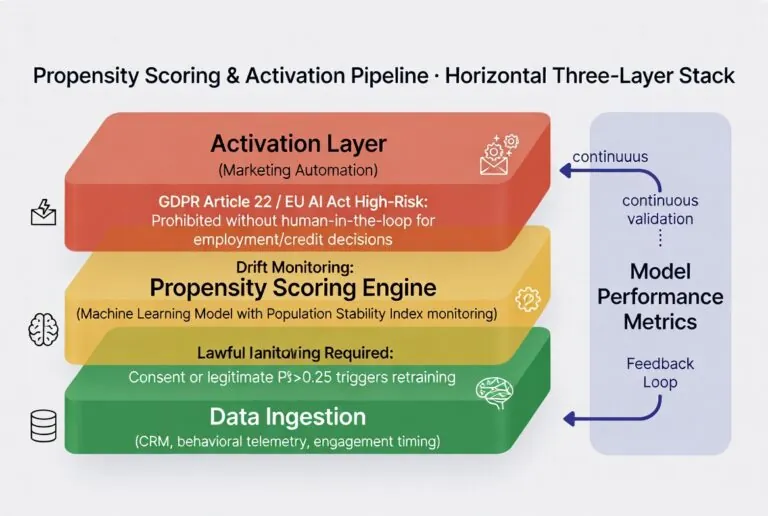
Predictive behavioral segmentation operates through three distinct technical layers. Understanding where each layer creates compliance exposure matters as much as understanding how each layer creates commercial value.
Layer 1 — Feature Engineering
Systems ingest first-party transactional data, CRM records, behavioral telemetry (scroll depth, dwell time, cross-device session stitching), and contextual signals (device type, time-of-day patterns). Unlike demographic segmentation using stable attributes, behavioral features capture transitional states—a user viewing pricing pages after months of content consumption indicates escalating purchase intent regardless of declared demographics. This is also where GDPR exposure concentrates: the moment dwell time or scroll velocity links to an identifiable individual, it’s personal data subject to purpose limitation and transparency requirements. → First-Party Data Strategy
Layer 2 — Propensity Modeling
Logistic regression provides interpretability for regulatory compliance audits; gradient boosting handles high-dimensional sparse data common in behavioral telemetry. Scores update continuously, creating “segment mobility” where customers fluidly transition between high-intent and at-risk cohorts. The critical operational risk here is model drift: the Population Stability Index (PSI) measures distribution shift between training and production data. PSI values exceeding 0.25 indicate significant drift requiring immediate model retraining—the threshold at which production accuracy collapses faster than most teams realize. → Model Monitoring
Layer 3 — Activation Governance
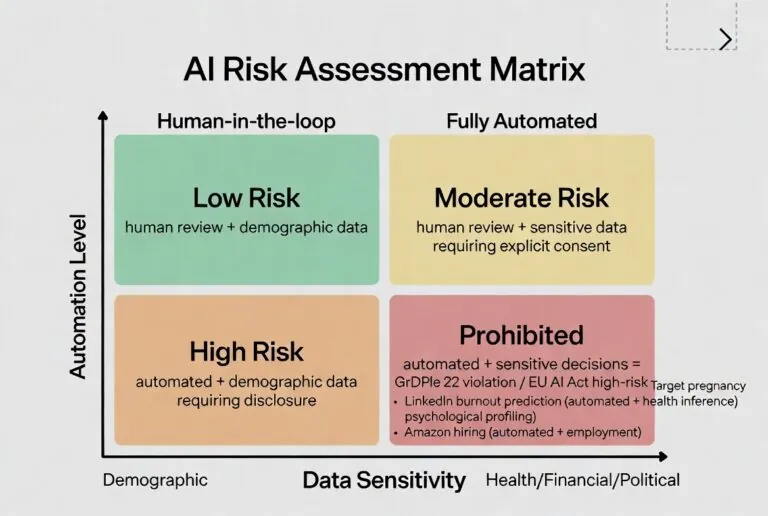
This is where most implementations fall short on both compliance and commercial grounds. High-intent segments receive differentiated treatment, but GDPR Article 22 requires human-in-the-loop review when automated decisions produce legal or similarly significant impacts—particularly in employment, credit, or insurance contexts. The threshold for human intervention must be defined before deployment, not retrofitted after a regulator asks.
Three Failure Modes Where Correct Technique Produces Catastrophic Outcomes
These aren’t implementation errors. They’re inherent risks of the technology that surface when deployed in specific contexts. They’re worth naming precisely because they all passed internal technical review before failing in production.
Amazon’s AI recruiting tool used machine learning to screen resumes by identifying patterns in ten years of historical hiring data. The algorithm performed exactly as designed—it detected patterns that predicted successful hires based on historical outcomes. Because the historical data reflected systemic gender imbalances in technical roles, the system learned to systematically downgrade resumes containing the word “women’s” (as in “women’s chess club captain”) or referencing women’s colleges—despite identical qualifications. Amazon’s engineers attempted bias correction but ultimately scrapped the entire project in 2017 after determining the system could not be rendered reliably unbiased.
Machine learning systems optimize for historical pattern reproduction. When historical patterns contain discrimination, the algorithm amplifies it with mechanical efficiency. The training data was the liability, not the model architecture.
Uber deactivated driver accounts using automated fraud detection algorithms that analyzed facial recognition data, location patterns, and transaction histories. Three drivers—one from Portugal and two from the UK—challenged their terminations under GDPR Article 22. In April 2023, the Amsterdam Court of Appeal ruled that Uber must provide transparency into the automated dismissal decisions, including meaningful information about the logic, factors considered, and their respective weighting.
GDPR Article 22 protections for automated employment decisions are not theoretical. Courts will require algorithmic transparency retroactively when companies fail to build it proactively—at significantly greater legal and operational cost.
Clearview AI created a facial recognition database from 30+ billion images scraped from public websites—LinkedIn, Facebook, news sites—without notification or consent, then processed these into biometric identifiers for law enforcement matching. The Dutch DPA’s €30.5M fine confirmed that “publicly available” data provides zero legal exemption under GDPR Article 9 for biometric processing. Clearview’s argument that it lacked EU corporate presence was rejected explicitly.
GDPR Article 3(2) extraterritoriality extends to any behavioral profiling system monitoring EU residents, regardless of company domicile. The “we’re not in Europe” defense died in this case.
Dual-Layer Enforcement: GDPR and EU AI Act Operating Simultaneously
Since February 2, 2025, predictive behavioral segmentation faces two parallel regulatory frameworks, not one. Understanding where they overlap—and where they diverge—is now a prerequisite for compliance architecture. → EU AI Act Guide
| Dimension | GDPR (since 2018) | EU AI Act (from Aug 2026) |
|---|---|---|
| What it regulates | Data processing and individual rights over personal data | AI system risk classification and governance obligations |
| Primary obligation for behavioral segmentation | Valid legal basis (consent or legitimate interest), transparency, purpose limitation, Article 22 right to explanation for automated decisions | Conformity assessment, bias monitoring, human oversight, technical documentation for “high-risk” AI systems |
| Prohibited practices (active since Feb 2025) | Processing sensitive data without explicit consent; opaque automated decisions with significant impact | Social scoring; emotion recognition in workplaces; biometric categorization inferring protected attributes; predictive crime assessment from profiling alone |
| High-risk classification triggers | Sensitive data; large-scale profiling; systematic monitoring | AI Act Annex III, Article 6(3): “always high-risk” when the system profiles individuals in employment, credit, insurance, education, or law enforcement contexts |
| Max penalty | €20M or 4% of global annual turnover (Art. 83(5) — the tier for violations of Articles 5–7; Art. 83(4) is a lower €10M/2% tier for procedural obligations) | €35M or 7% of global annual turnover for prohibited practices; €15M or 3% for high-risk violations |
| Do penalties stack? | Yes, GDPR and the AI Act apply simultaneously — but the AI Act’s own tiers don’t stack with each other. Combined exposure: up to €35M (GDPR + AI Act high-risk) or up to €55M (GDPR + AI Act prohibited practice), depending on classification. | |
The EU AI Act’s prohibited practices took effect February 2, 2025, banning social scoring systems, emotion recognition in workplaces, biometric categorization based on sensitive attributes, and predictive crime assessments based solely on profiling. The high-risk system obligations—conformity assessments, bias monitoring, human oversight requirements, technical documentation—become enforceable August 2, 2026. Note that the European Commission’s Digital Omnibus package — a legislative proposal, not adopted law, still under negotiation as of April 2026 — could delay Annex III high-risk obligations until December 2027 for some categories. Treat August 2026 as the binding deadline for compliance planning regardless: the proposal has not passed, and building a compliance timeline around an unconfirmed delay is how organizations end up scrambling in Q3 2026. → AI Act Checklist
Critically, AI Act Article 6(3) states that an Annex III AI system “shall always be considered to be high-risk” where it performs profiling of natural persons. This removes ambiguity: any behavioral segmentation system used in employment screening, credit decisions, insurance underwriting, or educational access is automatically high-risk. It doesn’t matter whether the segmentation is a primary input or a secondary feature.
The August 2026 Penalty Stack: GDPR and the AI Act, Reconciled
After August 2, 2026, a single AI agent processing personal data as a high-risk system can trigger violations under both GDPR and the EU AI Act simultaneously — the two regimes don’t merge into one fine. But within the AI Act itself, a system is classified once: it’s either high-risk (Annex III) or engaged in a prohibited practice (Article 5), not both, so those two AI Act tiers don’t stack on each other. A company deploying an AI recruiting agent — a high-risk use case, not a prohibited one — without proper documentation faces up to €20M under GDPR Article 83(5) for the underlying processing violation, plus up to €15M under AI Act Article 99(4) for failing to complete the required FRIA and conformity assessment — both obligation failures sit inside that same high-risk penalty tier. Combined exposure for that scenario: up to €35M, not €55M. The €35M/7% AI Act ceiling only applies if the system itself falls under a prohibited practice — a separate, higher track, reserved for things like social scoring or workplace emotion recognition, not ordinary high-risk profiling done badly.
Source: Paperclipped.de, March 2026 — DPIA and FRIA compliance analysis.
This creates a new compliance trigger that didn’t exist before: deploying a behavioral segmentation system in employment or credit contexts now requires two formal impact assessments, not one. GDPR Article 35 has required Data Protection Impact Assessments (DPIAs) since 2018. The AI Act adds a Fundamental Rights Impact Assessment (FRIA) under Article 27 for high-risk AI deployers. France’s CNIL has stated explicitly that for high-risk AI systems involving personal data, conducting a DPIA is “in principle necessary”—not recommended.
| Use Case | GDPR Risk | AI Act Classification | Required Actions |
|---|---|---|---|
| E-commerce purchase-intent scoring | Moderate — requires legal basis and transparency | Limited risk | Valid consent or LIA; privacy notice; opt-out mechanism |
| Churn prediction (SaaS customers) | Moderate — purpose limitation applies | Limited risk | Legal basis documentation; data minimization; purpose binding |
| Credit or insurance underwriting via behavioral signals | HIGH — Art. 22 applies; explicit consent likely required | High-risk (Annex III) | DPIA + FRIA; conformity assessment; human-in-the-loop; transparency report; EU database registration |
| Recruitment screening with behavioral telemetry | HIGH — automated employment decisions; Art. 22 mandatory | High-risk (Annex III) | DPIA + FRIA; conformity assessment; bias monitoring; human review mandate |
| Workplace productivity behavioral scoring | HIGH — systematic employee monitoring | High-risk (Annex III) | DPIA + FRIA; works council consultation (DE/NL); conformity assessment; transparency obligations |
| Social scoring or emotion recognition at work | HIGH — likely illegal without extensive justification | PROHIBITED — Feb 2025 | Do not deploy. Fine up to €35M or 7% global turnover. |
Compliance Architecture: Three Non-Negotiable Elements
Organizations that treat predictive behavioral segmentation as purely technical optimization—maximizing model accuracy without governance architecture—face compounding liabilities. Those implementing risk-calibrated frameworks will capture sustainable competitive advantage while competitors absorb enforcement actions. The architecture requires three structural elements. → Personalization Compliance Hub
1. Temporal Governance — Continuous PSI Monitoring
Model drift is a compliance risk, not just a performance risk. A model trained on 2023 behavioral data that now produces significantly different score distributions in 2025 may be making inferences that no longer correspond to the purpose stated in your privacy notice—a purpose limitation violation. Implement Population Stability Index monitoring with PSI thresholds: values exceeding 0.25 require immediate retraining review; values between 0.10 and 0.25 warrant investigation. Build this into your Data Protection Impact Assessment as a documented ongoing obligation, not a one-time event at deployment. → Model Drift Guide
2. Human-in-the-Loop Thresholds — Defined Before Deployment
GDPR Article 22 and AI Act Annex III requirements converge on the same operational demand: automated routing of high-stakes decisions to human review must be specified in advance. This means defining, in documentation the DPA can audit: which score thresholds trigger human review, what information the reviewer receives, what override capacity exists, and how override decisions are logged. The Uber case demonstrated the retroactive cost of not building this proactively. The post-August 2026 regulatory environment means that retroactive cost now includes AI Act conformity assessment failure stacked on top of GDPR penalties.
3. Geographic Compliance Mapping — No Safe Harbor in Domicile
Post-Clearview, domicile provides no safe harbor. Organizations must map every behavioral segmentation pipeline against the locations of data subjects, not the location of servers or corporate headquarters. For US-based organizations serving EU users: GDPR Article 3(2) applies. For any organization using Standard Contractual Clauses for EU-US data transfers, Transfer Impact Assessments are now required to verify SCCs provide adequate protection against third-country government access—a materially higher burden than pre-2023 practice.
- Classify all behavioral segmentation AI systems under EU AI Act risk tiers (prohibited / high-risk / limited / minimal)
- Complete DPIA under GDPR Art. 35 for all high-risk segmentation systems
- Complete FRIA under AI Act Art. 27 for all high-risk AI systems processing personal data
- Finalize conformity assessment and technical documentation for Annex III systems
- Register high-risk AI systems in the EU AI database (Art. 49)
- Implement PSI monitoring with documented thresholds and retraining triggers
- Define and document human-in-the-loop thresholds for all high-stakes automated decisions
- Complete Transfer Impact Assessments for all EU-US behavioral data flows
Where This Market Goes: Three Forces Reshaping Behavioral Segmentation by 2027
The August 2026 deadline creates a market bifurcation point—not just a compliance hurdle. Understanding what follows requires looking at converging pressures from below, regulatory inflection from above, and a fundamental shift in how “behavioral data” is architecturally sourced.
Contextual targeting resurges as the compliance-safe alternative. The structural shift is already measurable: the Consent Management Platform market is projected to grow from $802 million in 2025 to $3.59 billion by 2033, driven by organizations replacing invasive behavioral profiling with consent-gated first-party data and AI-driven contextual matching. Contextual targeting—aligning advertisements with page content rather than individual behavioral histories—eliminates Article 3(2) extraterritorial exposure entirely because it doesn’t generate profiles of identifiable individuals. That’s not a capability retreat; for EU-market advertising, it’s a structural advantage. → Contextual Targeting
Privacy compliance software itself becomes a growth market. The GDPR compliance software market, valued at $3.37 billion in 2025, is projected to reach $28.43 billion by 2035 at 23.78% CAGR—growth driven directly by the dual-framework enforcement environment described in this article. Vendors embedding PSI monitoring, automated DPIA generation, and real-time AI Act risk classification into their stacks are capturing first-mover advantage before August 2026 forces the market to move. Microsoft’s 2025 Compliance Manager updates, which improved automation accuracy by 40% according to Global Growth Insights, are one early signal of this consolidation.
Agentic AI creates the next compliance frontier. Gartner’s forecast that organizations will shift to “agentic segmentation”—AI systems autonomously identifying micro-segments and drafting interventions—by 2027 introduces a liability dimension the current GDPR/AI Act framework partially addresses but doesn’t fully resolve. When AI agents make segmentation decisions without human initiation, the documented “human-in-the-loop” becomes structurally harder to demonstrate. German regulatory ambiguity around AI Act enforcement authority—as of March 2026, the national supervisory authority for the AI Act has not been formally designated, with the Bundesnetzagentur the leading candidate but not yet confirmed—signals that agentic AI compliance architecture will face evolving interpretations well into 2027. Organizations building governance frameworks now, before agentic deployment at scale, will face significantly lower retrofit costs than those who wait. → Agentic AI in Personalization
Frequently Asked Questions
What exactly is predictive behavioral segmentation? +
Predictive behavioral segmentation uses machine learning to group customers based on their likelihood to take future actions—purchasing, churning, upgrading, or converting—using real-time behavioral signals rather than static demographics. Unlike traditional segmentation that categorizes customers as they currently exist, predictive systems forecast intent as it develops, enabling proactive interventions. The compliance complication: “behavioral signals” including dwell time, scroll velocity, and cross-device session data constitute personal data under GDPR the moment they’re associated with identifiable individuals—which they typically are in any commercial implementation.
What caused LinkedIn’s €310 million fine? +
The Irish Data Protection Commission found that LinkedIn processed personal data for behavioral analysis and targeted advertising without a valid legal basis under GDPR Articles 5 and 6. Specifically, LinkedIn tracked granular behavioral signals (dwell time, scroll speed, engagement patterns) to infer psychological states and professional propensities without obtaining proper user consent, violating transparency and purpose limitation requirements. The critical finding: inference-based profiling that predicts psychological states from behavioral telemetry falls squarely within GDPR’s scope, even when individual signals seem innocuous in isolation.
How does the EU AI Act affect behavioral segmentation specifically? +
Two ways. First, prohibited practices (effective February 2, 2025): social scoring, emotion recognition in workplaces, biometric categorization inferring protected attributes, and predictive crime assessments based solely on profiling are banned with fines up to €35M or 7% of global turnover. Second, high-risk classification: under AI Act Article 6(3), any segmentation system listed under Annex III that profiles individuals in employment, credit, insurance, education, or law enforcement contexts is automatically classified as high-risk. This requires conformity assessments, bias monitoring, human oversight, technical documentation, and EU database registration—all due by August 2, 2026.
Do GDPR and EU AI Act fines stack? +
Yes, but not in the way “stacking” usually gets described. GDPR and the AI Act are separate regimes that both apply to the same system, so their penalties add together. GDPR Article 83(5) allows fines up to €20M or 4% of global annual turnover for the kind of processing violations LinkedIn was fined for. The AI Act’s Article 99 adds up to €15M or 3% for high-risk system obligation failures (missing FRIA, missing conformity assessment), or up to €35M or 7% if the system instead falls under a prohibited practice — but a given system is classified as one or the other, not both, so those two AI Act figures are alternatives, not additional layers on each other. A high-risk recruiting AI missing its DPIA, FRIA, and conformity assessment faces up to €35M combined (GDPR €20M + AI Act €15M); a prohibited-practice system faces up to €55M combined (GDPR €20M + AI Act €35M). Legal analysis from March 2026 confirms GDPR and AI Act penalties don’t merge into one figure, but the AI Act’s internal tiers still depend on classification.
What is the “creepiness threshold” and why does it still matter in 2026? +
The “creepiness threshold” occurs when predictive accuracy reveals the surveillance mechanism, converting relevance into consumer reactance. Target’s 2012 pregnancy prediction case exemplifies this structurally: the algorithm achieved high accuracy predicting pregnancy from purchase patterns, but when customers discovered the inference, the accuracy backfired commercially. Target subsequently mixed pregnancy-related coupons with unrelated offers to disguise algorithmic precision. In 2026, this dynamic now has a legal analog: GDPR’s transparency requirement operationalizes the “don’t reveal the mechanism” problem into a mandatory disclosure obligation. The challenge is no longer whether to disclose—you must—but how to disclose in ways that satisfy regulators without triggering the consumer reactance Target encountered.
How do you prevent model drift in production? +
Implement Population Stability Index (PSI) monitoring to detect when production data distributions shift from training baselines. PSI values exceeding 0.25 indicate significant drift requiring immediate model retraining review. Values between 0.10 and 0.25 warrant investigation. Beyond technical monitoring, model drift now has a compliance dimension: a materially drifted model may be making inferences that no longer correspond to the stated purpose in your privacy notice, creating a purpose limitation violation under GDPR Article 5(1)(b). Document PSI thresholds and retraining triggers in your DPIA as ongoing obligations, not just deployment-time checks.
Enforcement Timeline: From GDPR Activation to AI Act Full Applicability
GDPR takes full effect across the EU. Article 22 automated decision-making protections become enforceable. DPIAs mandated for high-risk processing. Total fines since: €7.1B as of December 2025.
Irish DPC establishes that behavioral telemetry (dwell time, scroll speed) inferring psychological states constitutes personal data requiring valid legal basis. Official DPC announcement →
2025
Social scoring, workplace emotion recognition, biometric categorization inferring sensitive attributes, and predictive crime assessment from profiling alone are banned. Fines up to €35M or 7% global turnover. European Commission →
2025
Notified bodies and conformity assessment system must be operational. General-purpose AI model obligations begin. National competent authority designation required.
2026
Conformity assessments, bias monitoring, human oversight, FRIA, and technical documentation mandatory for all Annex III high-risk AI systems. Penalty stacking with GDPR creates maximum combined exposure of up to €35M for high-risk violations, up to €55M if the system instead falls under a prohibited practice. AI Act Art. 6 →